MULTI-TENANT AI
ASSISTANT PLATFORM
Enterprise SaaS platform unifying conversational AI, Retrieval-Augmented Generation (RAG), multimodal processing, and multi-tenant business automation.
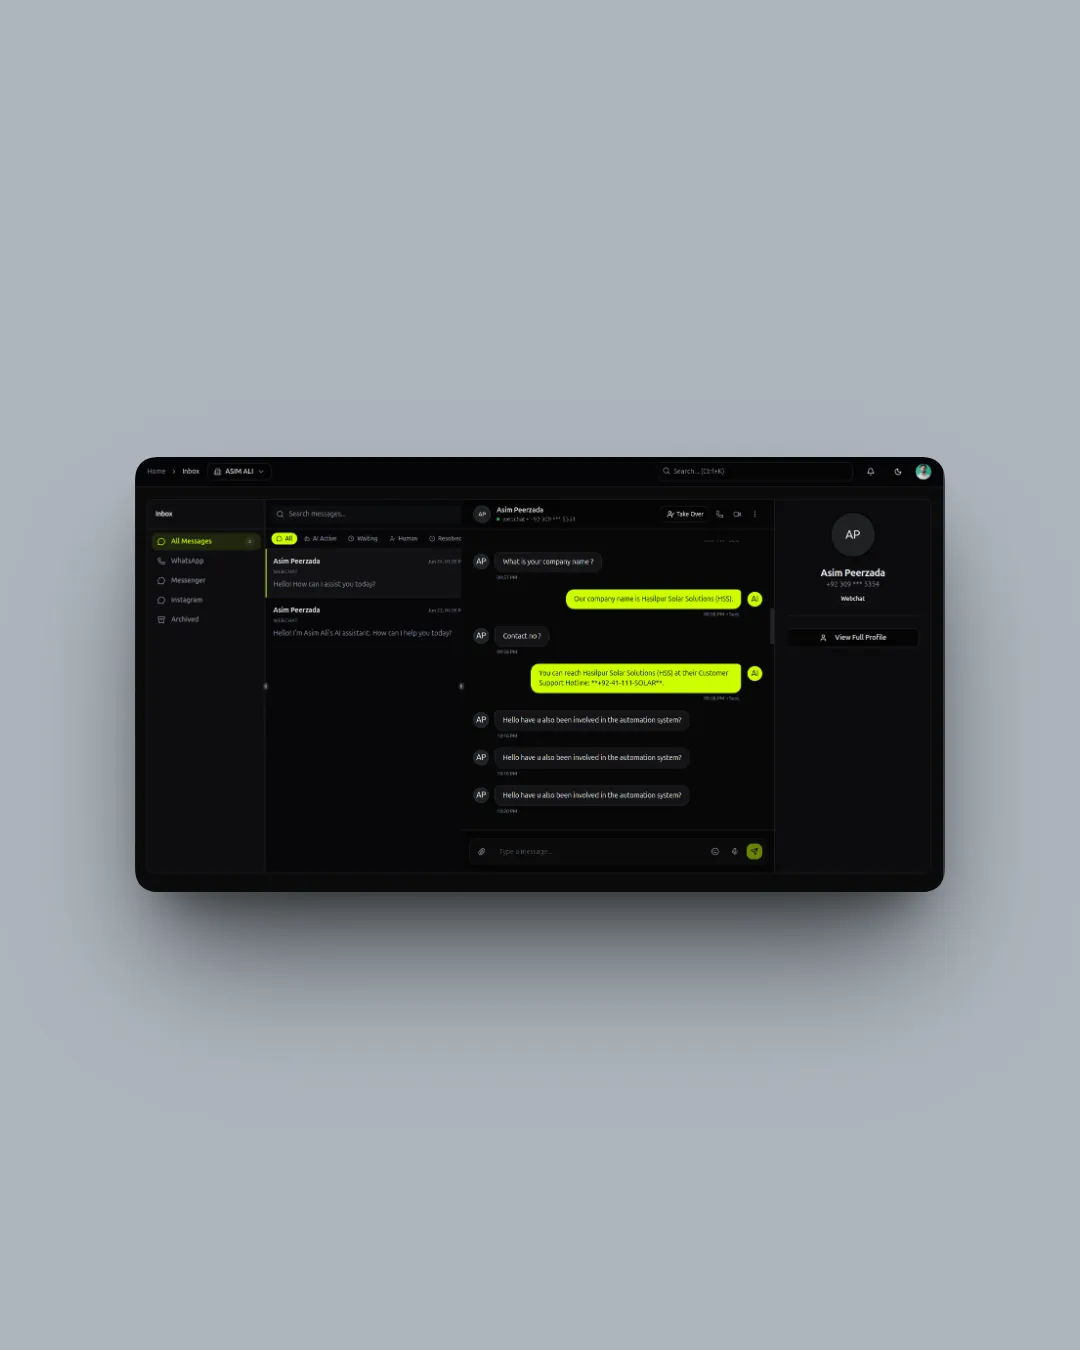
Operational Friction
Enterprises struggle to securely ground large language models in proprietary business documents while enforcing strict tenant data isolation, role-based controls, and voice interactions.
Engineered Solution
Architected a decoupled microservices architecture uniting a Laravel business API, a high-performance Python/FastAPI RAG engine, and a modern React operational UI.
Architecture & Backend Implementation
Full-Stack Architect & AI Lead: Designed decoupled microservices, FastAPI RAG vector pipelines, and tenant workspace security.
Decoupled Laravel business engine from Python/FastAPI AI compute microservice.
Built document chunking, embeddings, and Pinecone vector search with tenant isolation.
Integrated Whisper STT and ElevenLabs/OpenAI TTS for real-time speech interaction.
Implemented workspace data partitioning, audit logs, and Stripe subscription billing.
Key System Modules
Decoupled Microservices
Laravel core business engine paired with high-performance Python/FastAPI AI engine.
RAG Document Ingestion
Chunking, embedding, and vector retrieval grounded in tenant-isolated Pinecone indexes.
Multimodal Voice Pipelines
Real-time speech-to-text (Whisper) and text-to-speech (ElevenLabs) conversational engine.
Multi-Tenant Workspace RBAC
Strict data partitioning, workspace invitations, audit logging, and subscription billing.
Observability & Monitoring
Telemetry tracking token usage, vector query latency, and automated retry policies.
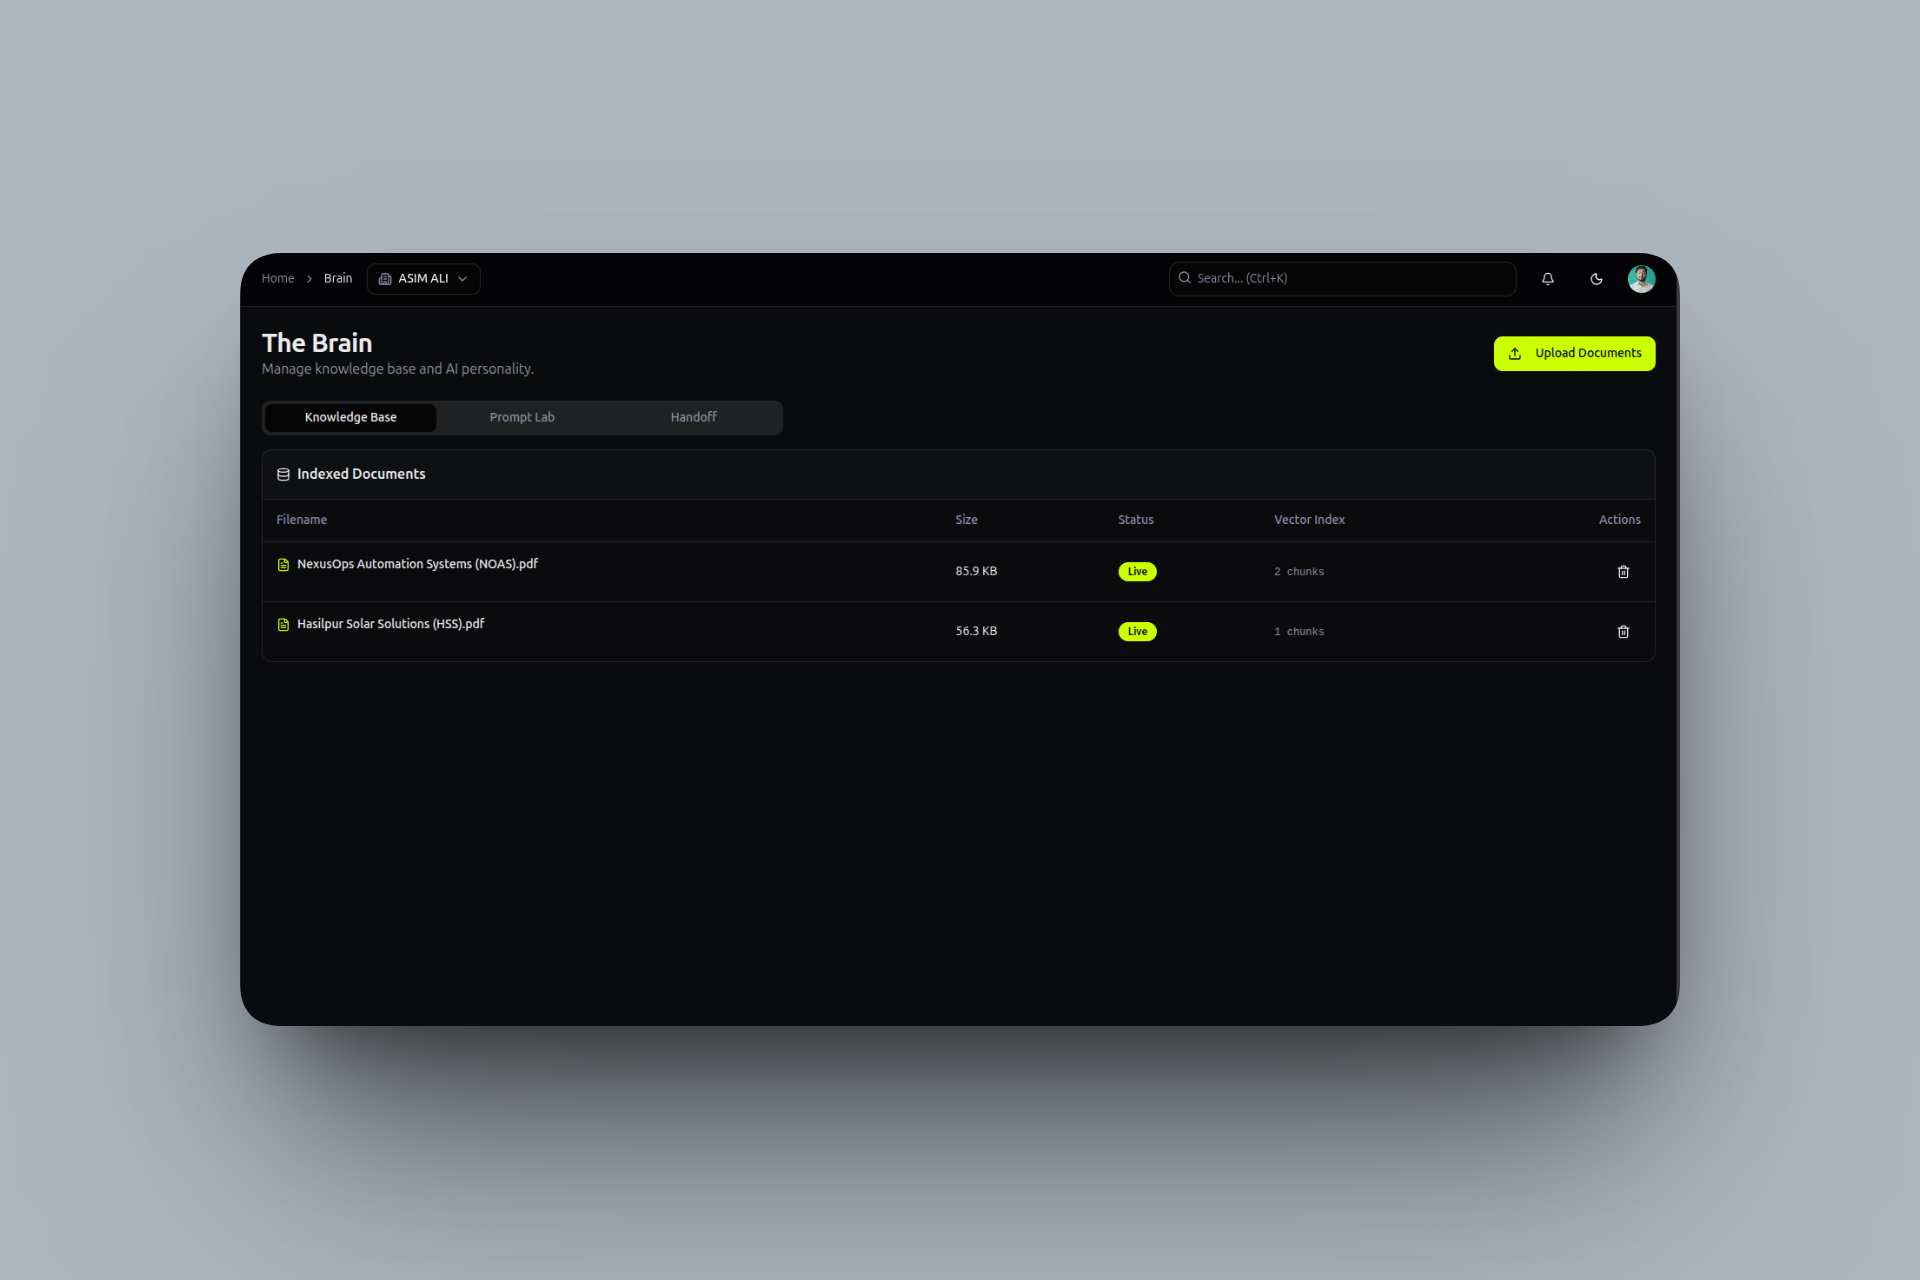
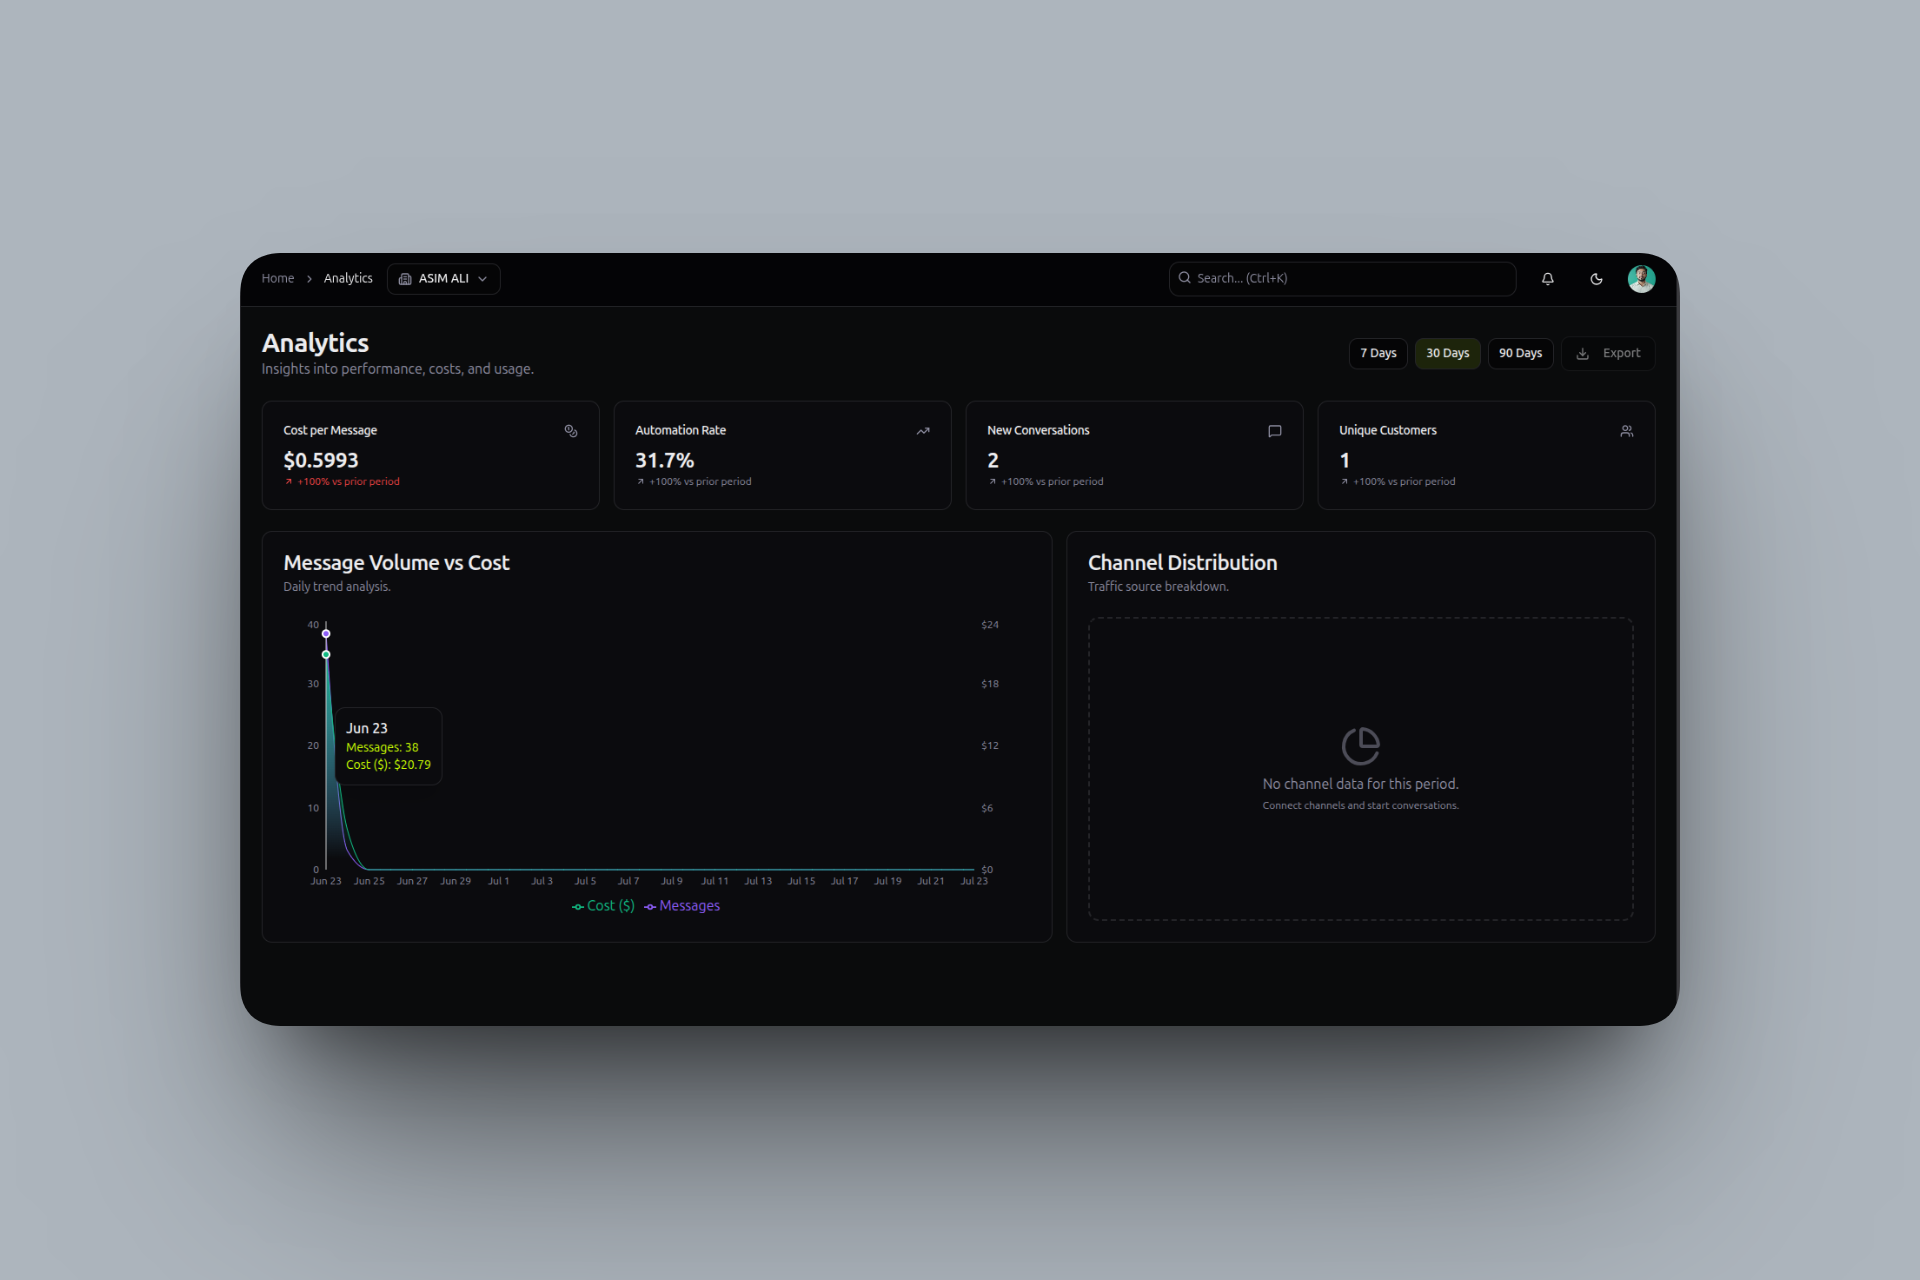
Operational Interfaces
System Topology & Data Flow
React 19 Operational UI & Chatbot Widget
Tailwind CSS · Vite · Audio Streaming Player
API & Authorization Layer
Laravel Business API & FastAPI AI Microservice Gateway
Vector RAG Pipeline
Document chunking, embeddings & Pinecone querying
Multimodal Voice Engine
Whisper STT & ElevenLabs TTS streaming
Billing & Quotas
Stripe webhook subscriptions & token rate limits
Relational & Vector Store
- •MySQL Tenant & User Relational Store
- •Pinecone Vector Database (Namespace Isolation)
- •Redis Context & Token Cache
AI & Speech Providers
- •OpenAI & Google Gemini LLMs
- •Whisper & ElevenLabs APIs
- •Stripe Billing Gateway
Technical Deep-Dive & Decisions
Tenant-Isolated Semantic Retrieval with Sub-500ms Response Latency
Executing semantic search across proprietary documents while strictly preventing cross-tenant data leakage and maintaining low conversational latency for real-time customer widgets.
Systematic Resolution
Implemented metadata filtering at the vector database query layer, ensuring vector lookups are strictly constrained to the authenticated tenant workspace ID alongside Redis caching for frequent context embeddings.
Intentional Design Choice
Decoupled the synchronous HTTP request from heavy embedding pipelines via background queue workers, providing immediate UI feedback during large document uploads.
Prioritization Rationale
Chose a dedicated Python/FastAPI microservice for AI computation rather than keeping everything in PHP, optimizing for native vector and ML library performance.
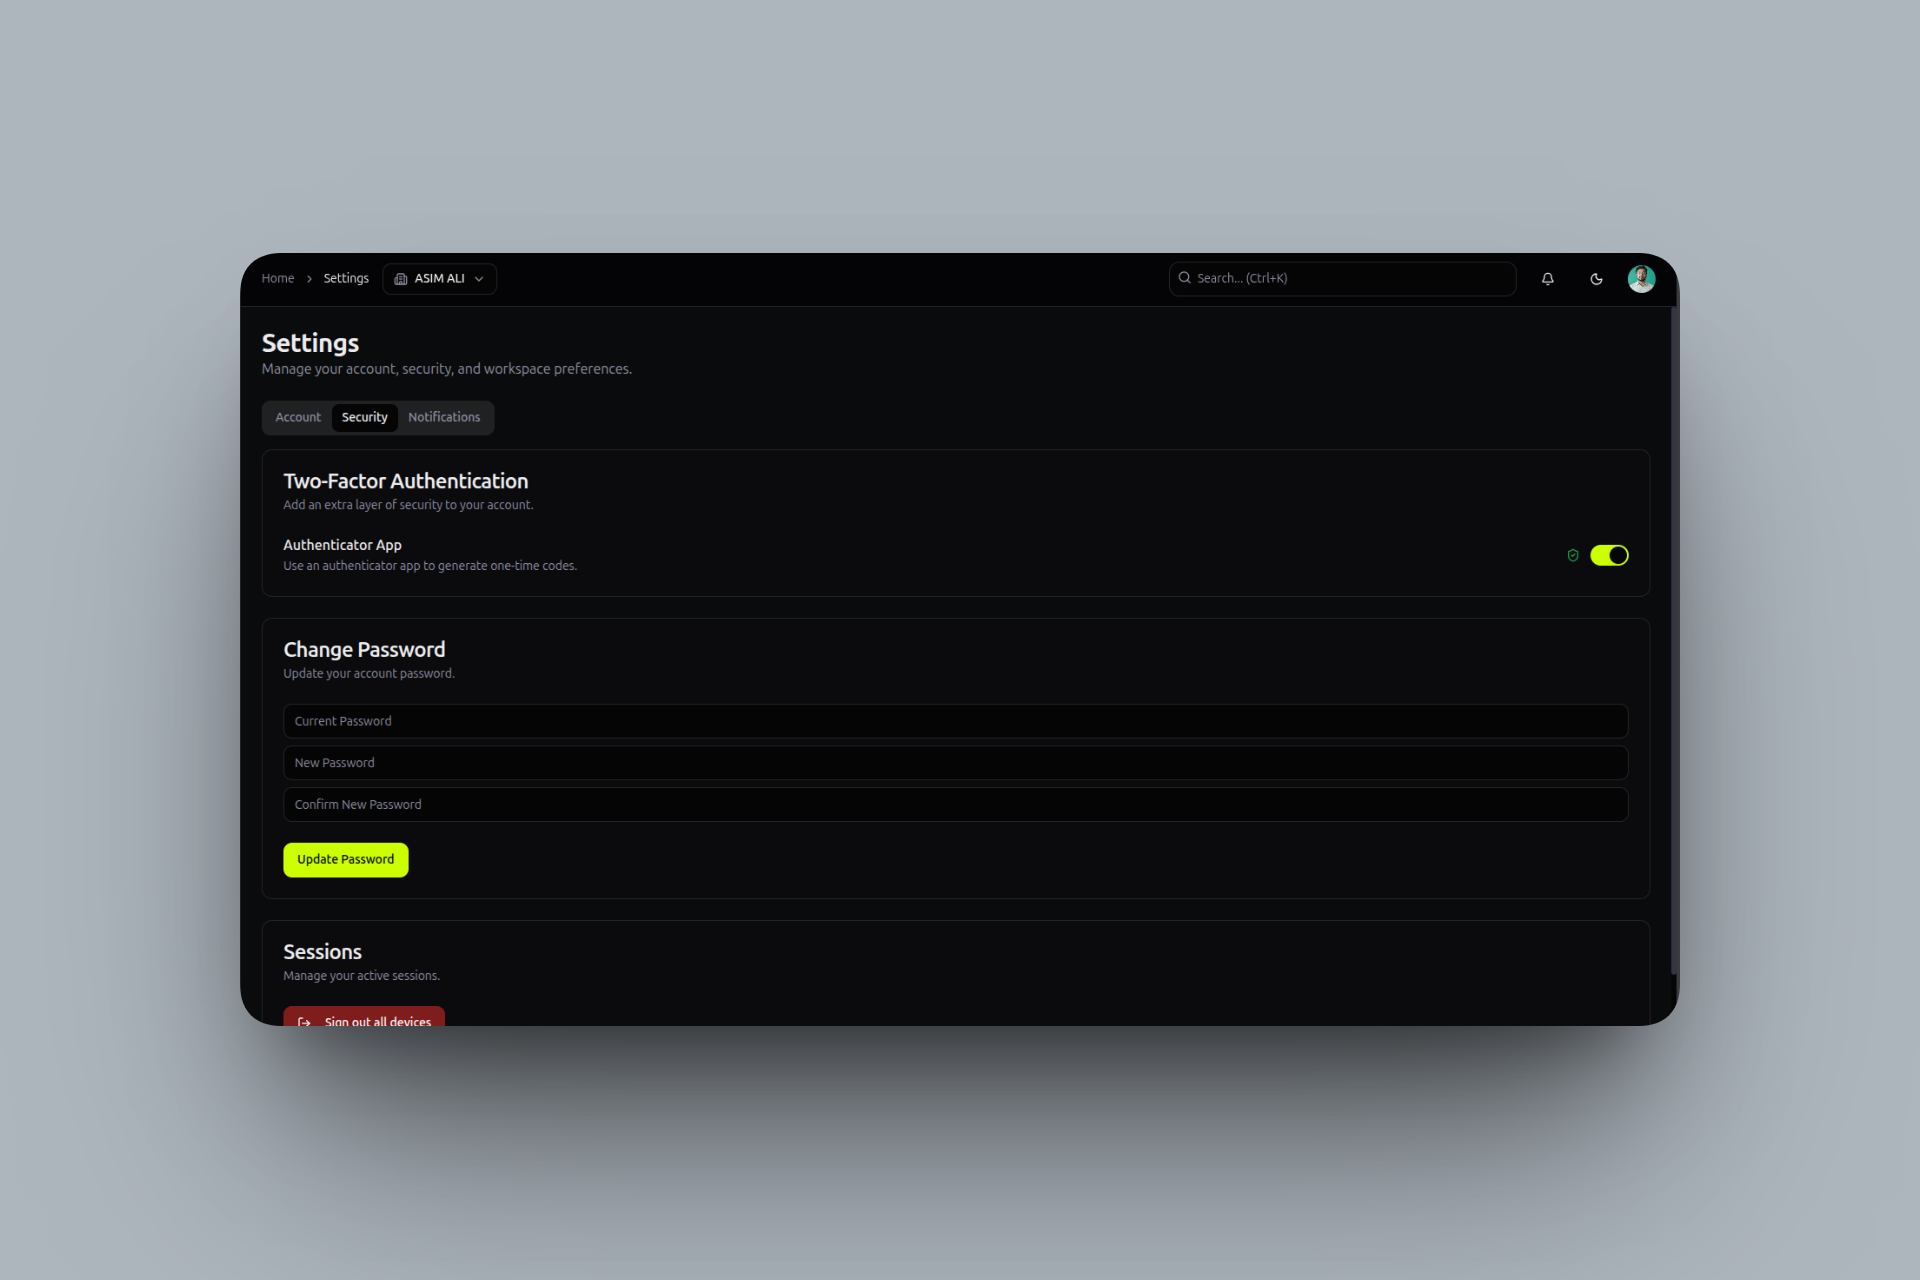
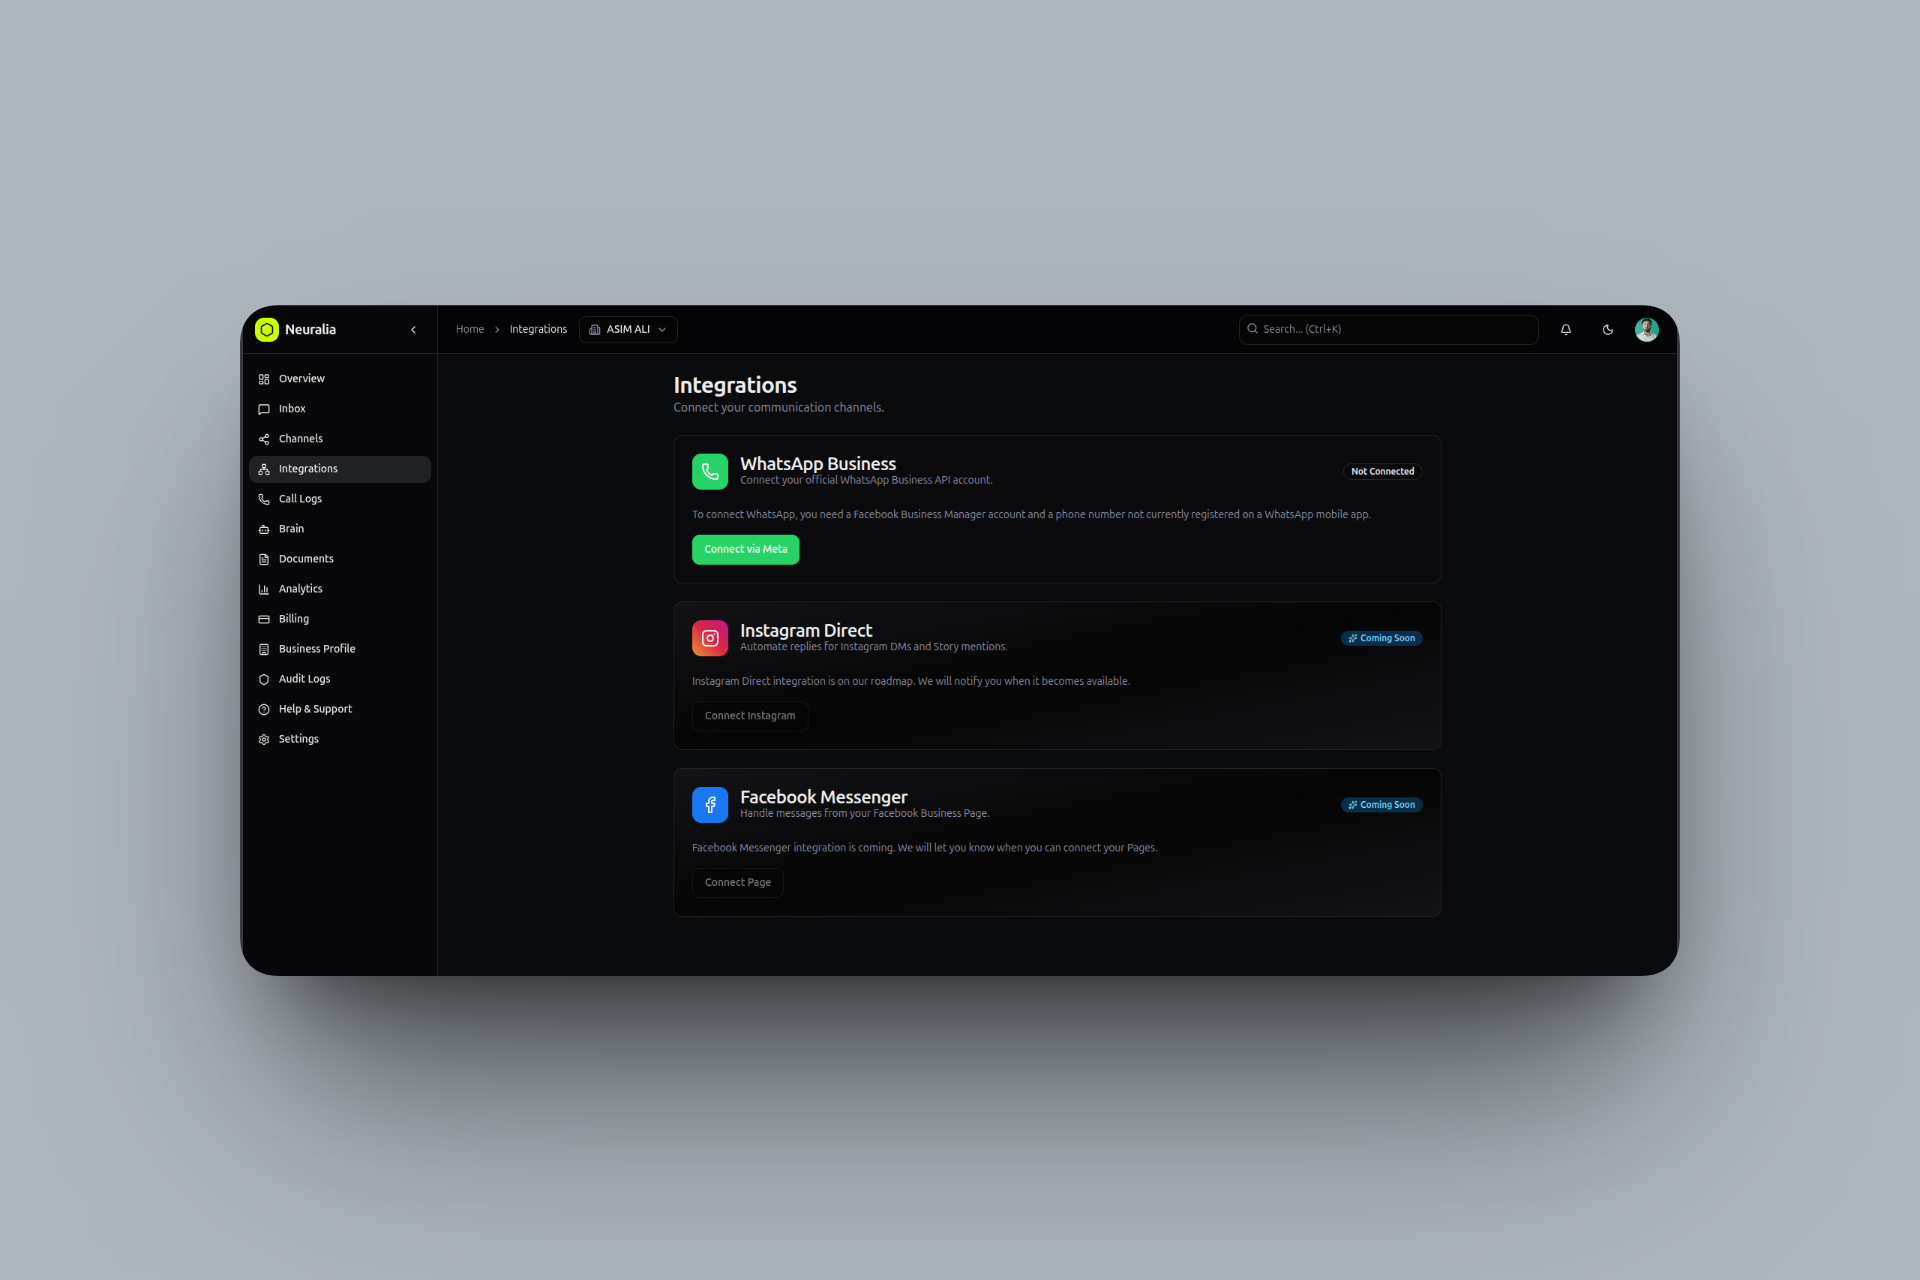
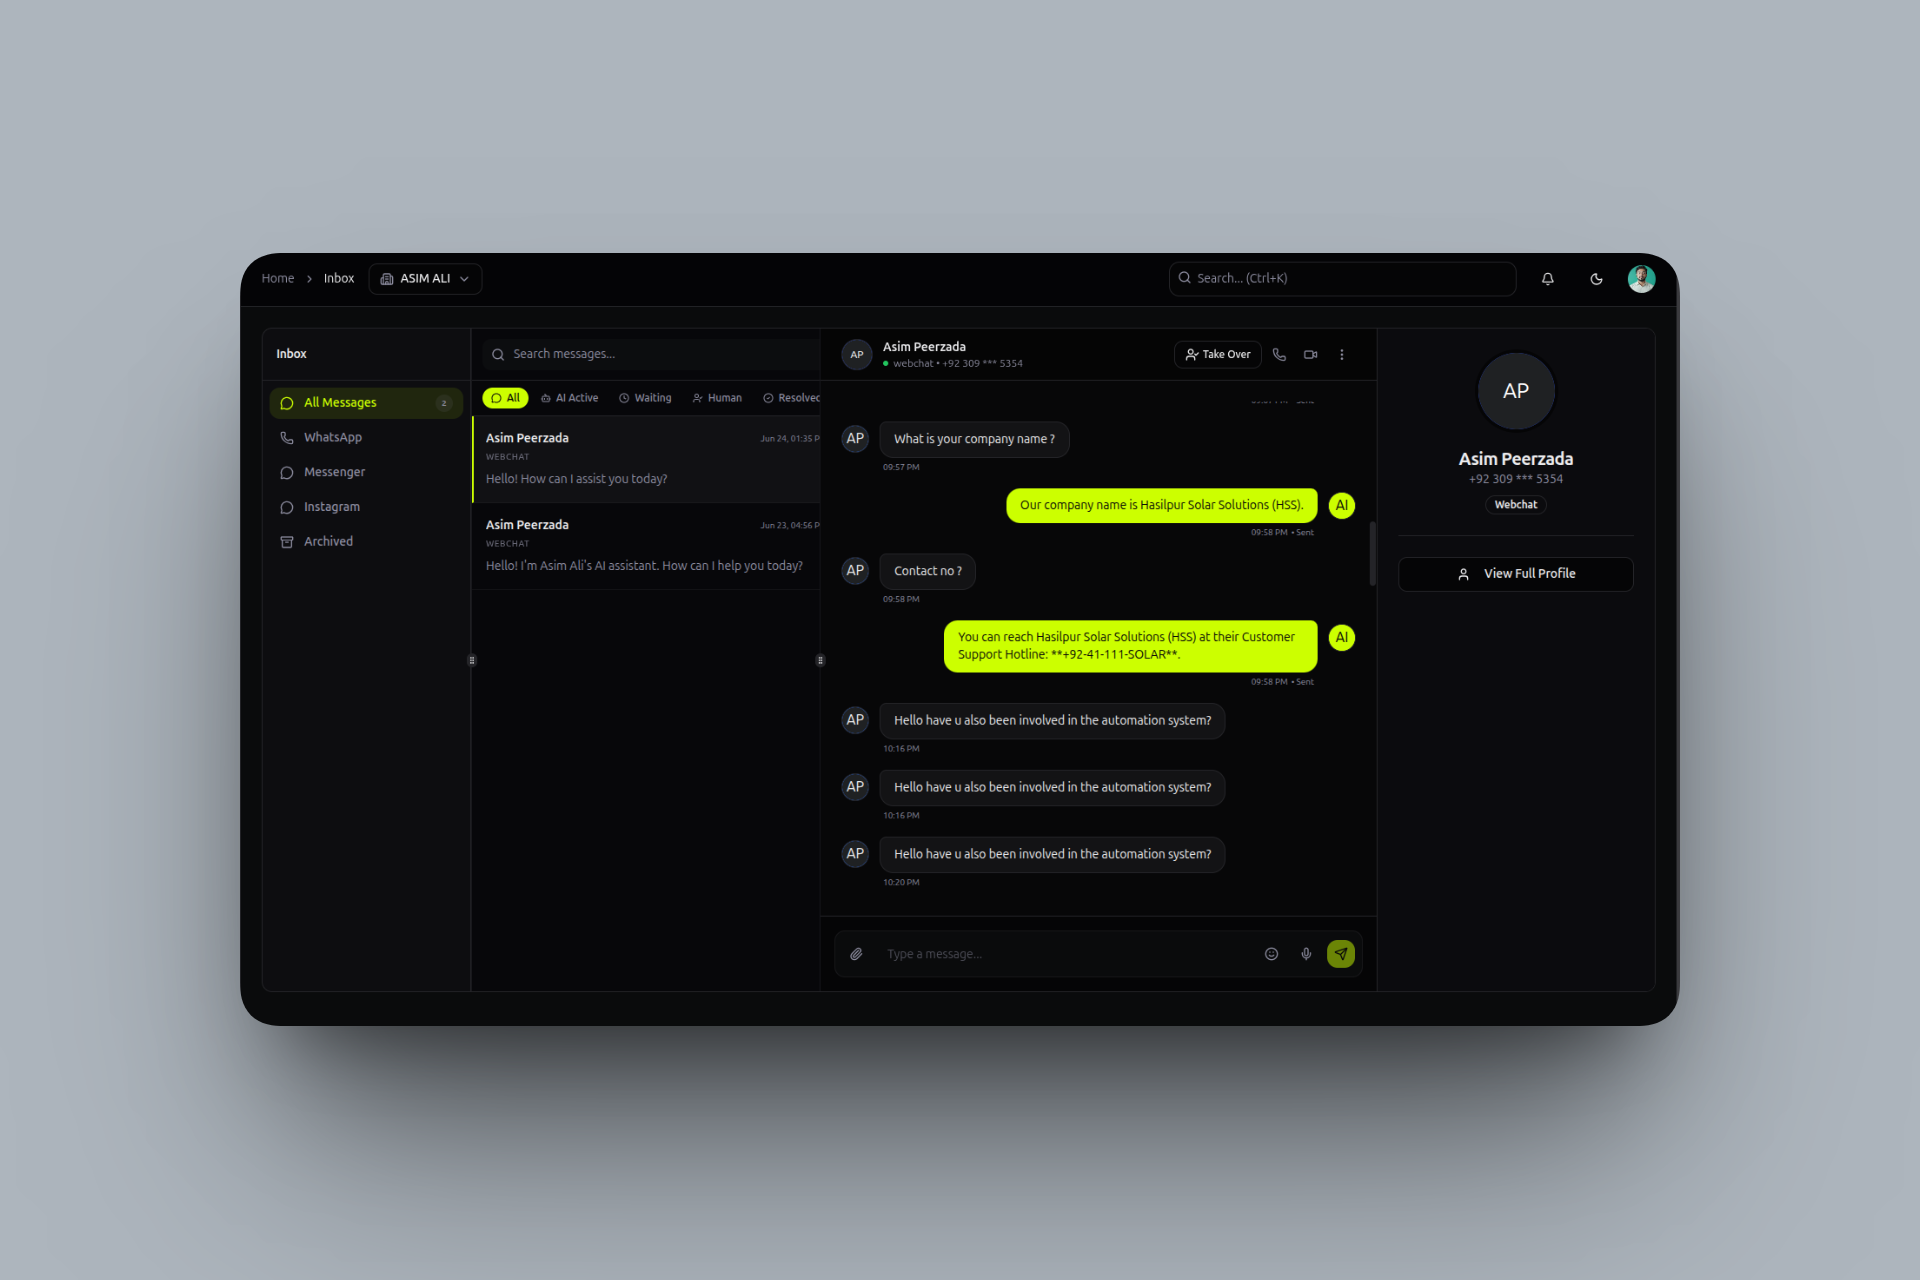
Expanded Application Views
Business & Operational Value
Enabled secure, enterprise-grade AI automation with isolated business knowledge bases, sub-500ms response latency, and multimodal voice capabilities.
Provided organizations with an auditable platform to ground generative AI in internal documentation safely.
Categorized Stack
LET'S BUILD
YOUR NEXT SYSTEM
Whether you are looking to architect a secure SaaS platform, integrate complex payment gateways, or automate operational workflows, I am ready to help.